Finite capacity scheduling for multi-plant operations
Head office sees free capacity at Plant 2; the planner sees a plant full until the 14th. What finite capacity scheduling means across plants, how central and local plans drift apart, and what keeps them connected.
 16 Oct 202616 min read
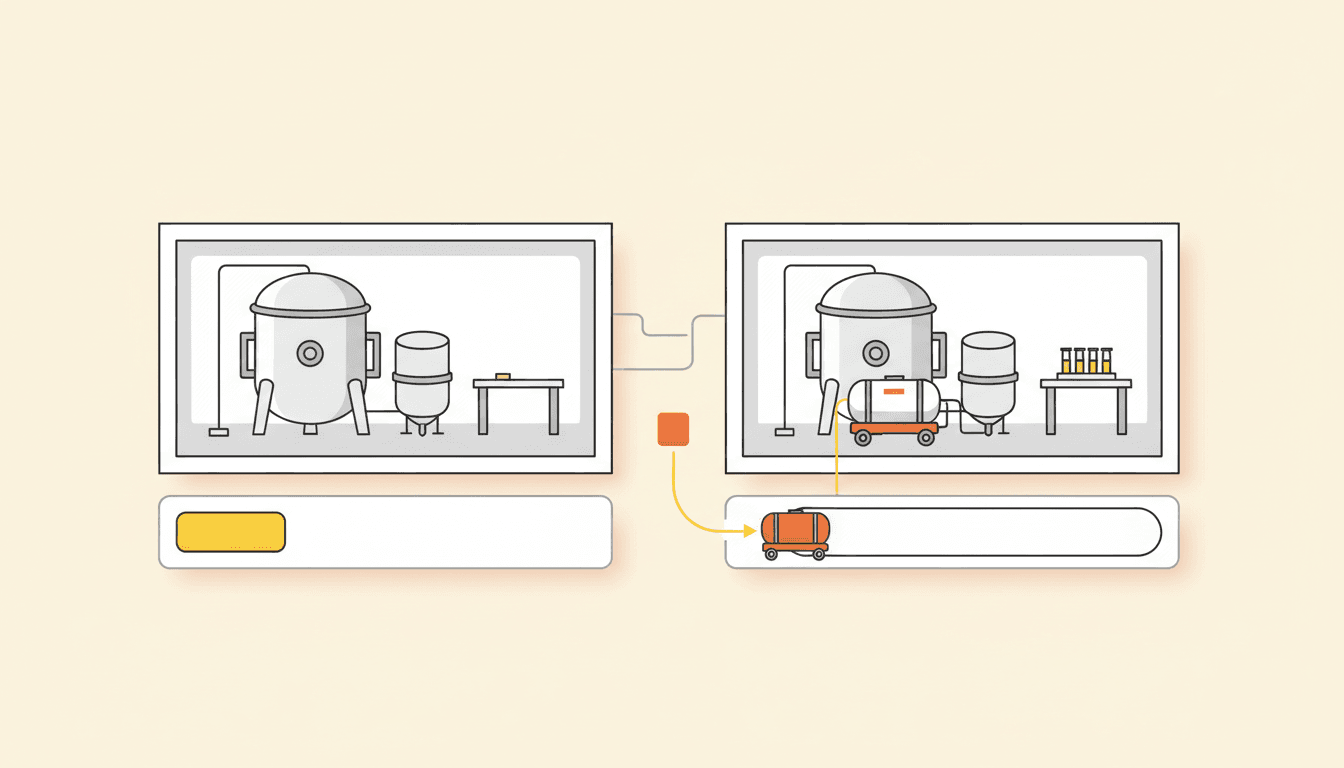
Here's a conversation that happens in more manufacturing companies than anyone likes to admit.
Head office looks at the plan and says, "Plant 2 can take that order. It's showing capacity."
Plant 2's planner looks at the same order and says, "We're already full until the 14th. Nobody asked us."
Both are looking at real data. They're just using different definitions of capacity. Head office sees hours on a calendar. The planner sees a reactor that needs a validated clean before the next product, a QC lab that can't release the previous batch until Thursday, and an operator team that's one person short on nights. That gap between the two definitions is exactly what finite capacity scheduling exists to close.
In a single plant, closing it is already real work. Across several plants, it's the difference between a network plan the business can trust and one that every site quietly rewrites.
What finite capacity scheduling actually means
The idea is simple, even if doing it well isn't. Finite capacity scheduling plans work against the real, limited capacity of each resource: this reactor, this packaging line, this QC lab, this crew, in this time window. It doesn't assume that if there's demand, the plant will somehow find the hours.
The opposite approach, usually called infinite capacity planning, does roughly that. It works out what needs to be made and when, and assumes the resources will be there. Material requirements planning (MRP) in most ERP systems works this way by default: it explodes demand, nets off inventory, and offsets start dates by a fixed lead time. Rough-cut capacity checks then compare total load against total hours, but they don't sequence anything.
That's not a flaw in ERP. It's what ERP planning was designed for: a coarse view of demand and materials over weeks and months. The trouble starts when that coarse plan gets treated as if it were an executable schedule.
A useful way to see the difference:
| Infinite capacity planning | Finite capacity scheduling | |
|---|---|---|
| Question it answers | What do we need, and by when? | What can actually run, where, in what order? |
| Treats resources as | Available, or a total-hours bucket | Specific assets with calendars and rules |
| Output | Dates and quantities | A sequence each site can execute |
| Typical horizon | Weeks to months | Hours to a few weeks |
| Breaks when | Someone treats it as the plan for the floor | It runs on stale data |
Both layers are needed. Problems start when there's no reliable bridge between them. (If you're still mapping which system does what, this comparison of APS, ERP and MES is a good starting point.)
Why capacity isn't one number, even in one plant
Before adding more plants, it helps to be clear about why a single plant's capacity can't be summarized as a percentage.
A plant can report 70% utilization on its reactors and still be full. The remaining 30% sits in windows where:
- the next product would need a 24-hour validated clean first, and the cleaning skid is already booked;
- the receiving tank still holds the previous intermediate, so the reactor has nowhere to discharge;
- the QC lab can't release the upstream batch in time, so there's nothing legal to charge;
- the only operators certified for that step are on a different shift.
In process manufacturing, capacity depends on sequence. A week running one product with one validated clean is a different plant from a week running four products with three cleaning windows. That's why a single "available hours" figure per site is the first thing to go wrong when capacity is rolled up to a network view.
Why multi-plant makes everything harder
With several plants, the same problem gets multiplied in ways that aren't obvious until you're in it.
Every plant has its own constraints, and they don't match
One site has a validated line for a product; another doesn't. One runs three shifts; another runs one. One has an in-house QC lab with next-day turnaround; another sends samples to a central lab and waits. One cleans with a dedicated skid per building; another shares one skid across the whole site.
"Capacity" isn't a single number you can add up across sites. It's a different set of rules at each one, and a network plan that ignores the rules is adding up numbers that don't mean the same thing.
Products can be made in more than one place, but not equally well
The same product might be approved at two plants, with different yields, different changeover burdens and different lead times. In regulated manufacturing, "approved" matters literally: a product can usually only be made at sites named in its registration, and adding a site can take months.
So deciding where an order should go is a scheduling decision, not just a sales one. The cheapest site on paper may be the one with the longest cleaning sequence for that product this month.
Plants share things that aren't obvious on a capacity chart
A central QC release team. A shared supply of a scarce raw material. A maintenance crew that travels between sites. An intermediate made at one plant and finished at another.
These are real constraints that cut across plants, and they rarely show up in any one plant's local schedule. Each site plans as if it has the shared resource to itself, and the conflict appears on the day two sites need it at once.
Central planning and local planning see different realities
Central teams see demand across the network but not the shop-floor detail. Local planners see the floor but not the network. Each makes reasonable decisions with the information they have, and the decisions still collide.
Neither side is wrong. They're working from different models of the same company.
How this usually goes wrong
The most common failure pattern isn't dramatic. It's a slow, quiet drift.
Central planning assigns volume to plants based on an approximate view of capacity. Each plant receives its share and builds a detailed local schedule, finding along the way that some of it doesn't actually fit. The local planner moves things around to make it work, which is exactly their job. But those changes rarely flow back up to the central view, so the next round of network planning starts from numbers that are already slightly wrong.
Repeat that over a few months, across several plants, and the central plan and the real plants are describing two different companies.
The drift shows up in recognizable symptoms:
- Phantom capacity. The network plan shows free hours that no site can actually use, because they sit behind a cleaning window, a full tank or a QC hold.
- Double promising. The same constrained resource, often a shared lab or a qualified line, gets committed to two orders because each commitment was made against a different view.
- Buffer creep. Sites protect themselves with extra safety stock and padded lead times. The plan stops being wrong in visible ways because everyone has quietly added slack, and working capital pays for it.
- Shadow schedules. The plan of record lives in ERP, but the plan the floor actually runs lives in a planner's spreadsheet. The spreadsheet isn't the problem. Depending on it as the live plan is.
- Reconciliation meetings. A weekly call exists mainly to bring central and local views back into line. By the time it ends, the plant has already moved again.
Each of these is a cost that never appears as one line on a P&L. Together they are a large part of what we've called the silo tax.
Two ways to structure multi-plant scheduling
A common instinct is to fix the drift with one giant schedule: put every site on a single Gantt chart and optimize the whole network at once. In process manufacturing, that usually makes things worse. Qualification, cleaning validation and licences are site-specific, so a model that treats sites as interchangeable produces plans no site can run.
There are two structures that work, and the right one depends on how material actually moves.
Site-level autonomy (the default). Each plant schedules against its own constraints: its own equipment, recipes, tanks, lab and maintenance windows. Network planning (S&OP, IBP or the weekly APS) still sets the boundaries: what to make, by when, at what priority. Each site adapts inside those boundaries, every day and every shift. A disruption at one site doesn't ripple into a sister site that doesn't share its materials.
Cross-site orchestration (when material flows between sites). When an intermediate is made in Plant A and finished in Plant B, or a bulk site feeds a packaging site, the plants are genuinely coupled. Then the schedule has to coordinate across them: shared intermediates, tank space at the receiving site, transport, and the qualified capacity each site has left. Each site still keeps its own frozen near-term plan, so a local problem at Plant B can't rewrite a campaign already running at Plant A.
Most networks need the first structure everywhere and the second only on specific product flows. Starting with the second, before each site's own constraints are modeled properly, is how multi-plant projects stall.
What good looks like
A few things show up consistently in multi-plant operations that handle this well.
Each plant's real constraints are modeled explicitly. Not a single capacity number per site, but the actual resources, calendars, validated product-to-line pairings, cleaning and changeover rules, tank capacities and lab availability that govern what can really run.
The network view and the plant view stay connected. Decisions made centrally are tested against local reality before they're committed. Changes made locally are visible centrally without anyone having to send a manual update.
Cross-plant dependencies are visible. If two sites depend on the same QC release team or the same scarce material, that dependency is part of the plan, not a surprise discovered when both plants need it on the same day.
Near-term plans are protected. Each site has a freeze horizon: the next shift or day that doesn't change unless something forces it. That stops a network re-plan from thrashing the floor.
Re-planning is fast. Things will change. A machine will go down at one site, a batch will fail at another. What matters is how quickly the impact on the rest of the network can be understood and acted on: ideally in minutes, not after a week of calls.
Planners stay in charge. The system proposes options and shows why. A planner can freeze an order, lock equipment or exclude an asset, and the next re-plan respects it. Nobody trusts a network schedule they can't override or explain.
A worked example: moving volume between plants
Here's how a common request plays out under each approach. The details are a composite for illustration.
A key customer pulls an order forward by two weeks. Plant 1, the usual source, is full. Head office looks at the network plan and sees that Plant 2 is approved for the product and shows 25% free capacity next week.
When the views are disconnected: the order is reassigned to Plant 2 on Monday. On Tuesday, Plant 2's planner finds that the free capacity sits after a campaign of a different product that needs a full validated clean before the switch, and the cleaning skid is booked for another line. On Wednesday, the central QC team, which also releases Plant 1's batches, says it can't take the extra samples until the following week. By Thursday, the order has a new, later date, a frustrated customer and three people who spent the week on calls.
When the views are connected: the reassignment is tested against Plant 2's live model before anyone commits. The test shows the cleaning conflict and the shared QC bottleneck in minutes. The planner sees two options: shift a smaller campaign at Plant 2 to free a clean window, or split the order with part made at Plant 1 after a minor resequence. Each option shows its knock-on effects on other orders. A decision is made on Monday, and it holds.
The difference isn't better people or more effort. It's whether the plan was checked against what each plant can actually run before it was promised.
What one site already teaches about the network
You don't need several plants to see this problem. Many large sites already behave like a network.
One large European API manufacturer ran several autonomous production units, separate buildings and lines on one campus, from a single annual plan built on sales projections and re-cut by hand. Each unit held its own constraints. Resources one unit couldn't reach in a given week sat idle while another covered its shortfall with safety stock and overtime. As the plant head put it:
We weren't running short of capacity. We were running short of a way to see, in real time, where the capacity actually sat.
The site added an event-driven scheduling layer beside the existing annual plan, not in place of it. Within four weeks of go-live, schedule rebuilds against live signals ran in minutes rather than days, and productivity gains showed within eight to twelve weeks. The full case study covers how.
A second site ran commercial production and a dedicated CDMO unit on shared equipment, all planned in Excel at overall-capacity level. A scheduling Control Tower fed from SAP ERP improved commercial lead time by 2.5%, and the freed equipment time was sold as five extra CDMO batches a year (case study). That site had no MES or SCADA feed in scope, which is a useful reminder that finite capacity scheduling doesn't have to wait for perfect plant data.
The lesson for multi-plant networks: get each site's constraints right first. Network-level coordination is only as good as the site models underneath it.
A quick way to check where you stand
Take your last significant network-level plan change, for example moving volume from one plant to another. Then ask four questions:
- How long did it take from the decision to everyone involved having an updated, realistic schedule?
- How confident was the team that the new schedule would actually hold?
- Where were the conflicts found: before the change was committed, or after?
- How many spreadsheets, calls or emails did it take to reconcile the central and local views?
If the honest answers are "several days," "not very," "after," and "too many to count," the planning layer between the network view and the plant floor isn't doing its job.
Where Bodhee fits
This is the layer Bodhee Production Scheduling is built for: finite capacity scheduling that models each plant's real constraints and re-plans in minutes when something changes. Quality Control Scheduling and Maintenance Scheduling can join the same live model of the plant, so a late QC release or a moved maintenance window re-plans production in the same pass.
For multi-plant networks, site-level autonomy is the default: each plant runs its own schedule against its own constraints. Cross-site orchestration is layered on where material genuinely flows between sites. Bodhee sits above MES and below planning, alongside the ERP, MES and LIMS systems already in place, not replacing them.
Bodhee is ISO 27001 certified and audit-trail-aligned with 21 CFR Part 11, EU GMP Annex 11 and GAMP 5, which matters in regulated multi-site environments. Details are in the Trust Center.
If your central plan and your plant schedules have started describing two different companies, that's usually the sign this layer is missing.
Request a Demo
Bring one plant's constraints and one recent network plan change. We'll show you how that change would have played out against a live model of the site.
Frequently asked questions
What is finite capacity scheduling?
Finite capacity scheduling plans work against the real, limited capacity of each resource (specific equipment, labs, people and utilities, in specific time windows) rather than assuming capacity will be available. Its output is a sequence a plant can actually execute, not just a set of dates.
What is the difference between finite and infinite capacity planning?
Infinite capacity planning, such as standard MRP, calculates what is needed and when, assuming resources are available. Finite capacity scheduling checks each order against what each resource can actually do. Infinite planning suits the long-range view; finite scheduling is needed for the plan a plant runs this week.
Should a multi-plant network be scheduled as one big model?
Usually not. In process manufacturing, qualification, cleaning validation and licences are site-specific, so sites are rarely interchangeable. A better structure is site-level autonomy as the default, with cross-site coordination only where material actually flows between plants.
How do you keep central planning and plant schedules in sync?
By testing central decisions against each plant's live constraints before they are committed, and by making local changes visible centrally without manual updates. The aim is one connected view, not a weekly reconciliation meeting.
Do we need to replace our ERP or APS to schedule across plants?
No. ERP and APS keep doing network and long-range planning. Finite capacity scheduling sits underneath them, turning their plan into executable site schedules and re-planning when the floor changes.
Do we need MES or live machine data to start?
No. Live data helps, but a site can start from ERP orders, master data and planner inputs, then add MES, LIMS and maintenance integrations over time. One of the sites above ran without an MES or SCADA feed.
Bodhee: Dynamic Manufacturing Scheduling
Bodhee delivers dynamic, constraint-aware scheduling for Production, Quality Control, and Maintenance on one live model of your plant.
See it in action
Production Scheduling
Explore the deployments, architecture, and ROI math behind dynamic scheduling for your plant.
See Production Scheduling